Company Name to Domain API
Find the website behind every company name from your AI assistant, no-code workflow or own code.
Copy a ready-made setup prompt
Pick your tool, copy the prompt and paste it in. The AI sets up a Datablist folder with the example code from GitHub. You only paste your API key into the file it creates.
Set up and run the Datablist "Company Name to Domain" API for me. The full setup instructions for AI assistants are in this GitHub repo: https://github.com/datablist/company-name-to-domain-api (follow skills/datablist-setup/SKILL.md).
Set up and run the Datablist "Company Name to Domain" API for me. The full setup instructions for AI assistants are in this GitHub repo: https://github.com/datablist/company-name-to-domain-api (follow skills/datablist-setup/SKILL.md). If you cannot run commands on my computer, guide me one copy-paste step at a time.
Set up and run the Datablist "Company Name to Domain" API for me. The full setup instructions for AI assistants are in this GitHub repo: https://github.com/datablist/company-name-to-domain-api (follow skills/datablist-setup/SKILL.md).
I am not a developer. Help me build a Make (make.com) scenario with HTTP modules that runs the Datablist "Company Name to Domain" API: find the website domain for every company name in my list.
Use the cURL section of the README in https://github.com/datablist/company-name-to-domain-api for every request: start a task, wait until it is completed, then read the results.
Store my API key in a Make connection, never in plain text, and never ask me to paste it into this chat. I get it from https://app.datablist.com/account/api.
Tell me which step to add and what to put in every field. Map domain, website and confidence to my columns.
I am not a developer. Help me build an n8n workflow with HTTP Request nodes that runs the Datablist "Company Name to Domain" API: find the website domain for every company name in my list.
Use the cURL section of the README in https://github.com/datablist/company-name-to-domain-api for every request: start a task, wait until it is completed, then read the results.
Store my API key as an n8n credential (header auth), never in plain text, and never ask me to paste it into this chat. I get it from https://app.datablist.com/account/api.
Tell me which step to add and what to put in every field. Map domain, website and confidence to my columns.
I am not a developer. Help me build a Zap with Webhooks by Zapier steps that runs the Datablist "Company Name to Domain" API: find the website domain for every company name in my list.
Use the cURL section of the README in https://github.com/datablist/company-name-to-domain-api for every request: start a task, wait until it is completed, then read the results.
Store my API key in the Zap's connection settings, never in plain text, and never ask me to paste it into this chat. I get it from https://app.datablist.com/account/api.
Tell me which step to add and what to put in every field. Map domain, website and confidence to my columns.
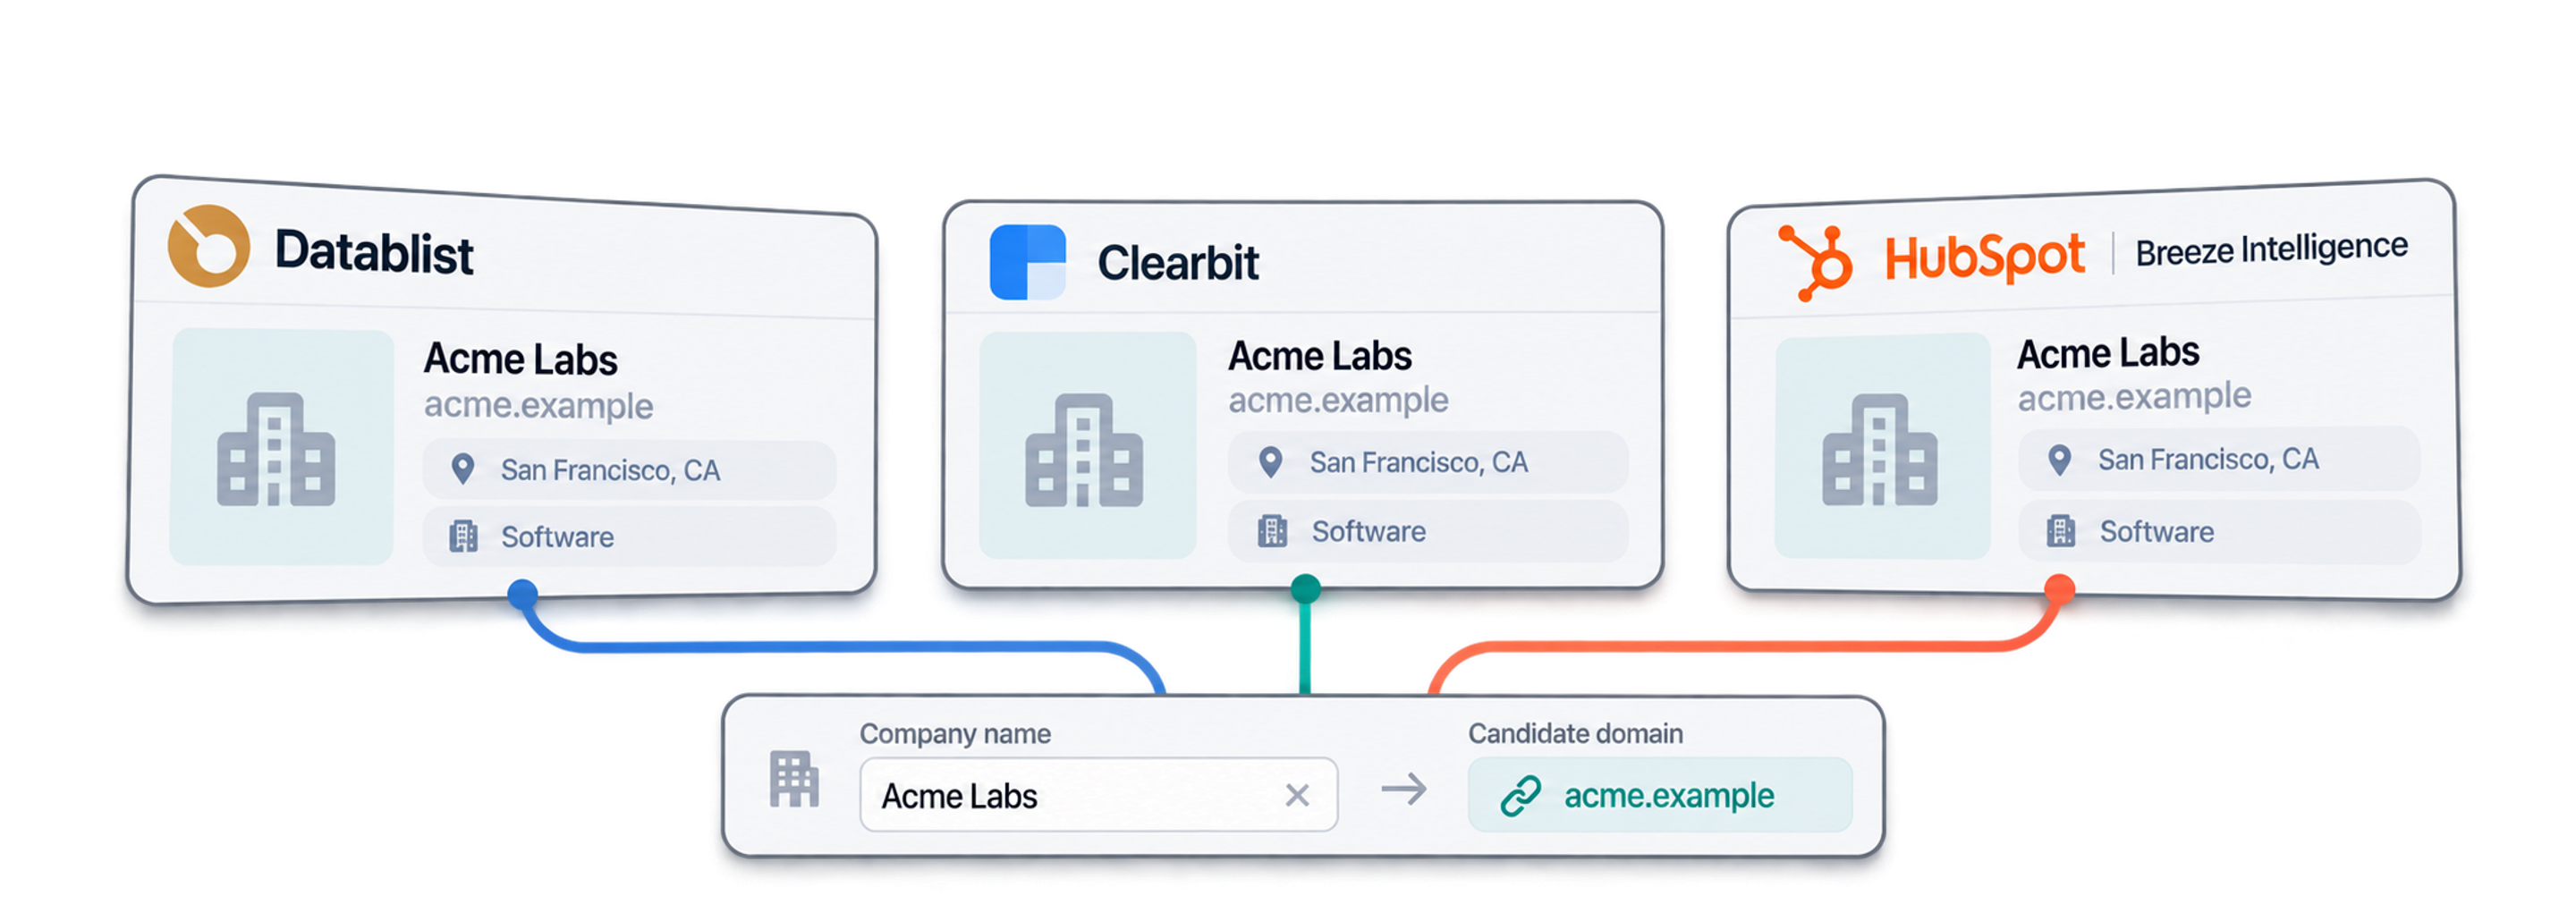
 From $0.001 per Domain
 Domain and Full URL
 10,000 Domains per Task



 Claude
 ChatGPT
 Cursor
 Make
 n8n
 Zapier
Your own code
Pick Your Way In
Let an AI assistant or your automation tool do the setup, or call the REST API from your own code.
Paste the setup prompt
Copy the prompt for Claude, ChatGPT or Cursor, or for Make, n8n or Zapier, and paste it in. The AI creates a Datablist folder on your computer and sets everything up.
Paste your API key
When the AI asks, copy your API key from the Datablist app and paste it into the .env file it opened. Never paste it into the chat.
Get your results
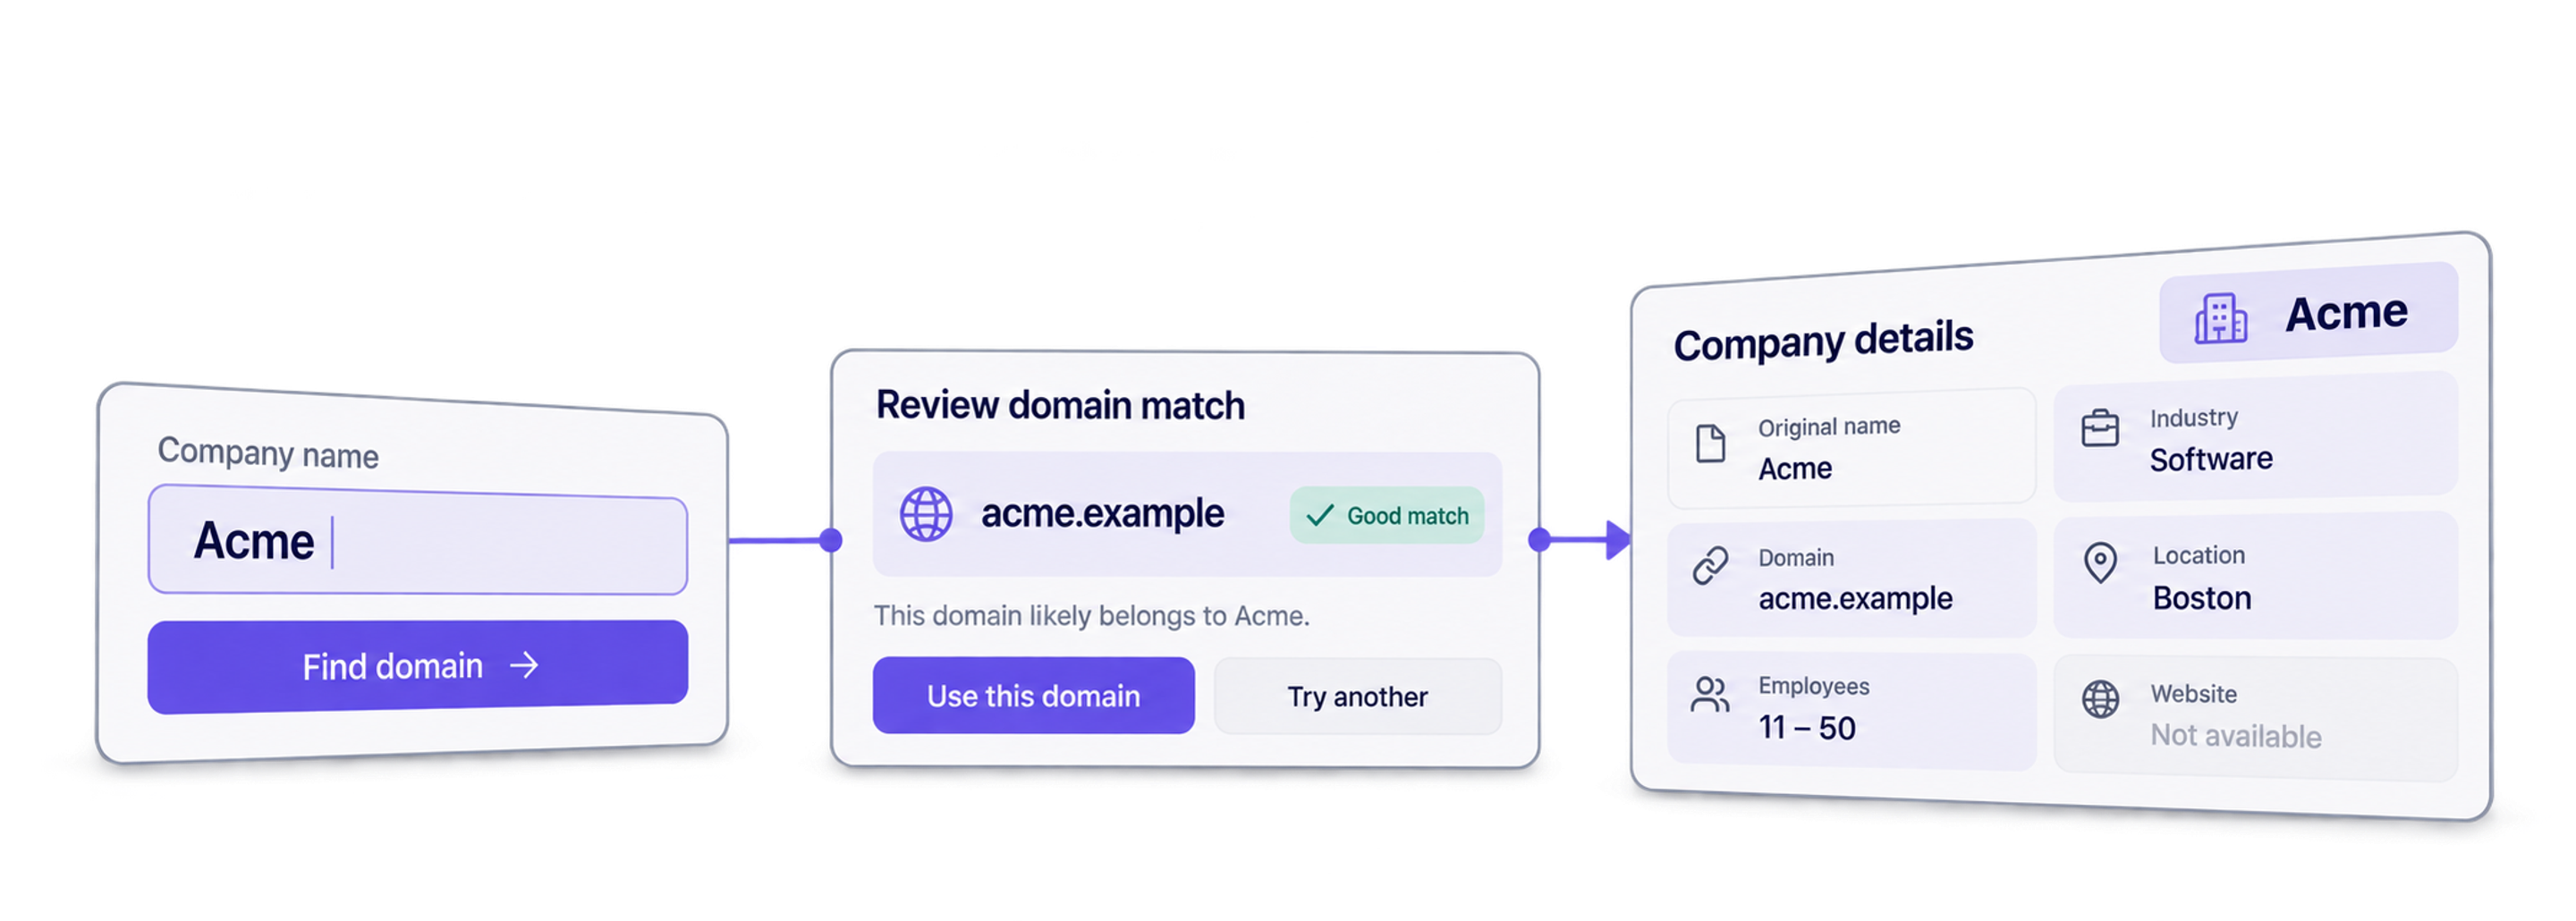
Send your list of names and get one row back per name: domain, website and a confidence level, ready for your sheet or CRM.
See a sample resultUsing Make, n8n or Zapier? Here is every field for the HTTP request
Use the HTTP request module or node your tool offers. You need three steps: send the list, wait, then read the results.
1. Send your list (HTTP request)
- Method
POST- URL
https://api.datablist.com/v1/enrichments/tasks- Headers
X-API-Key= your API keyContent-Type=application/json- Body (JSON)
{ "enrichmentId": "company-name-to-domain", "uniqueId": "company-name-to-domain-import-1", "settings": { "workflow": "dataset_google", "searchCountryCode": "US" }, "inputs": [ {"inputId": "row-1", "data": {"companyName": "Brightwave Analytics"}}, {"inputId": "row-2", "data": {"companyName": "Northpeak Logistics"}}, {"inputId": "row-3", "data": {"companyName": "Juniper & Vale Studio"}} ] }- Keep
- The
@idfrom the response. That is your task ID.
2. Wait until it is done
Add a short wait or delay, then a GET request to https://api.datablist.com/v1/enrichments/tasks/TASK_ID with the same X-API-Key header. Repeat until status is completed.
3. Read the results
GET https://api.datablist.com/v1/enrichments/tasks/TASK_ID/results?limit=50. Map outputs to your columns. If nextCursor is not empty, call again with &cursor= plus that value.
Create a task with one request. The full script with polling and results is in the developer section.
curl --request POST 'https://api.datablist.com/v1/enrichments/tasks' \
  --header 'X-API-Key: YOUR_PERSONAL_API_KEY' \
  --header 'Content-Type: application/json' \
  --data '{
    "enrichmentId": "company-name-to-domain",
    "uniqueId": "company-name-to-domain-import-1",
    "settings": {
      "workflow": "dataset_google",
      "searchCountryCode": "US"
    },
    "inputs": [
      {"inputId": "row-1", "data": {"companyName": "Brightwave Analytics"}},
      {"inputId": "row-2", "data": {"companyName": "Northpeak Logistics"}},
      {"inputId": "row-3", "data": {"companyName": "Juniper & Vale Studio"}}
    ]
  }'
import requests

response = requests.post(
    "https://api.datablist.com/v1/enrichments/tasks",
    headers={"X-API-Key": "YOUR_PERSONAL_API_KEY"},
    json={
      "enrichmentId": "company-name-to-domain",
      "uniqueId": "company-name-to-domain-import-1",
      "settings": {
        "workflow": "dataset_google",
        "searchCountryCode": "US"
      },
      "inputs": [
        {"inputId": "row-1", "data": {"companyName": "Brightwave Analytics"}},
        {"inputId": "row-2", "data": {"companyName": "Northpeak Logistics"}},
        {"inputId": "row-3", "data": {"companyName": "Juniper & Vale Studio"}}
      ]
    },
)
task = response.json()
print(task["@id"], task["status"])
const response = await fetch("https://api.datablist.com/v1/enrichments/tasks", { method: "POST", headers: { "X-API-Key": "YOUR_PERSONAL_API_KEY", "Content-Type": "application/json", }, body: JSON.stringify({ "enrichmentId": "company-name-to-domain", "uniqueId": "company-name-to-domain-import-1", "settings": { "workflow": "dataset_google", "searchCountryCode": "US" }, "inputs": [ {"inputId": "row-1", "data": {"companyName": "Brightwave Analytics"}}, {"inputId": "row-2", "data": {"companyName": "Northpeak Logistics"}}, {"inputId": "row-3", "data": {"companyName": "Juniper & Vale Studio"}} ] }), }); const task = await response.json(); console.log(task["@id"], task.status);
At a Glance
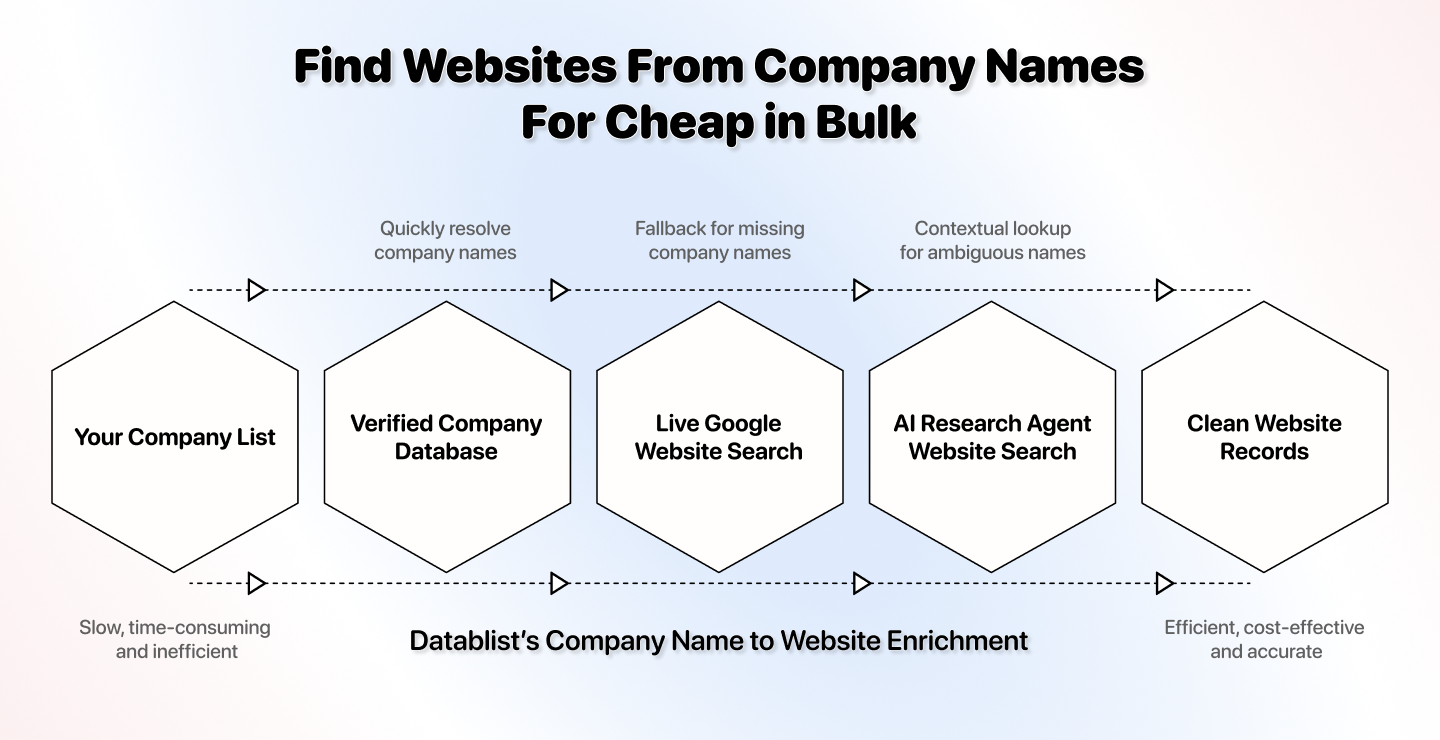
Return the domain and website matching the name. Filter on country to narrow results. Return the domain with the more traffic when several domains match. No Datablist workspace, collection or import needed.
- Company names: One per row, straight from your list, sheet or CRM
- A country (optional): Narrows the search, for example US or France
- Where to search: Our company dataset, Google, or both
- The domain: For example brightwaveanalytics.com
- The website: The full web address, ready to click
- A confidence level: High, Medium, Low or Very Low, so you know what to double-check
- Found in our dataset: 1 credit, only when a domain is found
- Searched on Google: 2.5 credits per name searched
- 1,000 credits = $1: Shared with the Datablist app
What Teams Build With It
Put Company Name to Domain wherever your data already flows.
What Will It Cost You?
Pay per lookup with credits. API access starts on the Growth plan.
How much will it cost you?
Tell us how many company names you need to resolve and we'll show you the cheapest way to get them.
Build It Into Your Code
Everything you need to call the REST API directly: code, responses, endpoints, fields, authentication and limits.
DATABLIST_API_KEY and run.Copy, Paste, Run
A complete script that creates a task, waits for it and prints every result. Replace YOUR_PERSONAL_API_KEY with your key.
# 1. Create the task (returns 202 Accepted and the task "@id")
curl --request POST 'https://api.datablist.com/v1/enrichments/tasks' \
  --header 'X-API-Key: YOUR_PERSONAL_API_KEY' \
  --header 'Content-Type: application/json' \
  --data '{
    "enrichmentId": "company-name-to-domain",
    "uniqueId": "company-name-to-domain-import-1",
    "settings": {
      "workflow": "dataset_google",
      "searchCountryCode": "US"
    },
    "inputs": [
      {"inputId": "row-1", "data": {"companyName": "Brightwave Analytics"}},
      {"inputId": "row-2", "data": {"companyName": "Northpeak Logistics"}},
      {"inputId": "row-3", "data": {"companyName": "Juniper & Vale Studio"}}
    ]
  }'

# 2. Poll every few seconds until status is completed, failed or stopped
curl 'https://api.datablist.com/v1/enrichments/tasks/TASK_ID' \
  --header 'X-API-Key: YOUR_PERSONAL_API_KEY'

# 3. Read the results, then follow nextCursor until it is null
curl 'https://api.datablist.com/v1/enrichments/tasks/TASK_ID/results?limit=50' \
  --header 'X-API-Key: YOUR_PERSONAL_API_KEY'
import time
import requests

BASE = "https://api.datablist.com/v1/enrichments"
HEADERS = {"X-API-Key": "YOUR_PERSONAL_API_KEY"}

# 1. Create the task
response = requests.post(f"{BASE}/tasks", headers=HEADERS, json={
  "enrichmentId": "company-name-to-domain",
  "uniqueId": "company-name-to-domain-import-1",
  "settings": {
    "workflow": "dataset_google",
    "searchCountryCode": "US"
  },
  "inputs": [
    {"inputId": "row-1", "data": {"companyName": "Brightwave Analytics"}},
    {"inputId": "row-2", "data": {"companyName": "Northpeak Logistics"}},
    {"inputId": "row-3", "data": {"companyName": "Juniper & Vale Studio"}}
  ]
})
response.raise_for_status()
task_id = response.json()["@id"]

# 2. Poll until the task finishes
while True:
    task = requests.get(f"{BASE}/tasks/{task_id}", headers=HEADERS).json()
    if task["status"] in ("completed", "failed", "stopped"):
        break
    time.sleep(5)

# 3. Read every result page
params = {"limit": 50}
while True:
    page = requests.get(f"{BASE}/tasks/{task_id}/results", headers=HEADERS, params=params).json()
    for result in page["results"]:
        print(result["inputId"], result["status"], result["outputs"])
    if not page["nextCursor"]:
        break
    params["cursor"] = page["nextCursor"]
// Node.js 18+ or any runtime with fetch. Keep your key on the server.
const BASE = "https://api.datablist.com/v1/enrichments";
const HEADERS = { "X-API-Key": "YOUR_PERSONAL_API_KEY" };
const sleep = (ms) => new Promise((r) => setTimeout(r, ms));

// 1. Create the task
const created = await fetch(`${BASE}/tasks`, {
  method: "POST",
  headers: { ...HEADERS, "Content-Type": "application/json" },
  body: JSON.stringify({
    "enrichmentId": "company-name-to-domain",
    "uniqueId": "company-name-to-domain-import-1",
    "settings": {
      "workflow": "dataset_google",
      "searchCountryCode": "US"
    },
    "inputs": [
      {"inputId": "row-1", "data": {"companyName": "Brightwave Analytics"}},
      {"inputId": "row-2", "data": {"companyName": "Northpeak Logistics"}},
      {"inputId": "row-3", "data": {"companyName": "Juniper & Vale Studio"}}
    ]
  }),
});
if (!created.ok) throw new Error(`Create failed: ${created.status}`);
const taskId = (await created.json())["@id"];

// 2. Poll until the task finishes
let task;
do {
  await sleep(5000);
  task = await (await fetch(`${BASE}/tasks/${taskId}`, { headers: HEADERS })).json();
} while (!["completed", "failed", "stopped"].includes(task.status));

// 3. Read every result page
let cursor = null;
do {
  const url = new URL(`${BASE}/tasks/${taskId}/results`);
  url.searchParams.set("limit", "50");
  if (cursor) url.searchParams.set("cursor", cursor);
  const page = await (await fetch(url, { headers: HEADERS })).json();
  for (const result of page.results) {
    console.log(result.inputId, result.status, result.outputs);
  }
  cursor = page.nextCursor;
} while (cursor);
What the API Returns
One result per input, with your inputId, a status, the outputs and the credits used. Sample data.
{
  "taskId": "00000000000040008000000000000001",
  "results": [
    {
      "inputId": "row-1",
      "status": "success",
      "outputs": {
        "companyDomain": "brightwaveanalytics.com",
        "companyUrl": "https://www.brightwaveanalytics.com",
        "domainConfidence": "High"
      },
      "creditsUsed": "1",
      "error": null
    }
  ],
  "nextCursor": null
}
Endpoints and Fields
All paths are relative to https://api.datablist.com. Field definitions come from GET /v1/enrichments/company-name-to-domain (schema version 2026-09-12).
/v1/enrichments/company-name-to-domainRead the schema, no key needed/v1/enrichments/tasksCreate a task/v1/enrichments/tasks/{taskId}Poll status and progress/v1/enrichments/tasks/{taskId}/resultsRead results, 1 to 100 per page/v1/enrichments/tasks/{taskId}/stopCancel a running task/v1/enrichments/tasksTask history, newest firstsettings once per task and one data object per input. Results can include extra fields as the enrichment evolves, so keep unknown keys when you parse outputs.Show all settings, inputs and outputs
workflowWorkflow |
Text | Datablist first uses a company dataset to match names with domains. Datablist might also perform a Google search on the remaining company names. One of: dataset_google, dataset, google. |
searchCountryCodeTarget Country |
Text | Narrow down the search to a specific country. This setting filters the company dataset and is a country setting for the Google Search fallback. |
countryOverwriteDefine target country per item. |
Boolean | When enabled, a “Target Country” input will be added to configure the target country for each item. You can enter a country using its ISO 3166 code (Alpha-2 like “FR“, or Alpha-3 like “USA“) or its full English name (like “Portugal“). If the country is missing or invalid, Datablist will use the global “Target Country” setting as a fallback. |
acceptNonRootAccept non root websites |
Boolean | By default, Datablist skips dataset and Google results that point to a page hosted below a domain the company does not own (eg: https://www.directory.com/mycompany). This is good to avoid company directories. But you can miss company websites that are hosted on platforms. For example: https://www.hostingplatform.com/mycompanypage. Use this setting to accept non-root websites while preserving and validating the full page URL.
👉 Datablist caches Google search results for 48 hours. If you change this setting after the first run, results come from the cache, costing only 1 credit. Applies when workflow is dataset_google or dataset or google. |
skipDomainsSkip following domains |
Text | Comma-separated list of domains. Datablist skips company directories (Crunchbase, etc.) and social networks (LinkedIn, Facebook, etc.) when scoring Google results. But it may miss industry-specific directories. Add your list of domains to skip, and they’ll be included with the default ones.
👉 Datablist caches Google search results for 48 hours. If you change this setting after the first run, results come from the cache, costing only 1 credit. Applies when workflow is dataset_google or google. |
onlyProcessCachedResultsOnly Process Google Cached Results |
Boolean | If enabled, Datablist will only use your saved Google search results from the cache. It won’t run new live searches. Use this to reduce costs and skip dataset results. Applies when workflow is google. |
companyNamerequiredCompany Name |
Text | The name of the company to search for (ex: google). |
targetCountryrequired when enabledTarget Country |
Text | Narrow down the search to a specific country. This setting filters the company dataset and is a country setting for the Google Search fallback. If the country is missing or invalid, Datablist will use the global “Target Country” setting as a fallback. Applies when countryOverwrite is true. |
companyDomainrequiredCompany Domain |
Text | The company domain (ex: google.com), when found. |
companyUrlrequiredCompany Full Url |
Text | The company full url (ex: https://www.google.com), when found. |
domainConfidenceDomain Confidence |
Text | Confidence level of the match: High, Medium, Low, or Very Low. |
One Header, Clear Limits
Create a Personal API Key in your Datablist account and send it on every authenticated request.
Authentication
Send your key in the X-API-Key header. Datablist exchanges and renews access tokens for you.
- Header: X-API-Key: YOUR_PERSONAL_API_KEY
- Optional: manage tokens yourself with Authorization: Bearer from POST /v1/account/token
- One or the other: sending both headers returns 400 AmbiguousCredentials
- Server side only: keep keys out of URLs, browser code and logs
Limits
- Inputs per task: 1 to 10,000
- Size: 16 KiB per input, 10 MiB per request
- Run time: up to 24 hours per task
- Task creation: 10 requests per 60 seconds per account
- Polling and results: 120 requests per 60 seconds per operation
- Active tasks: about 20 at once per account
- Retention: tasks and results are kept for 90 days

Related Tutorials
Learn the newest workflows with detailed step-by-step guides.
Frequently Asked Questions
Everything you or your AI coding agent need to integrate the Company Name to Domain API: auth, request, polling, results, limits and retries.
Related APIs, Enrichments and Free Tools
Chain Company Name to Domain with other enrichments, in your code, in the Datablist app or for free.
 Company Name Cleaner APIClean messy company names before you look up their domains.
 Company to LinkedIn APIMatch a company website with its LinkedIn company page, or the reverse.
 Waterfall Email Finder APIFind a verified work email from a name and the company domain.
- Company EnrichmentTurn a domain into industry, size, location, and founded year.
- Waterfall Email FinderUse the domain plus a name to find a verified email address.
- Company Name CleanerStrip LLC and Inc and fix casing before you run the lookup.
 Free Domain FinderPaste company names and find their websites. Free, no credit card required.
- Free Company Name CleanerNormalize company names: legal suffixes stripped, casing fixed, duplicates flagged.
- Free Email FinderFind a work email from a name and a company. Free to try.